Arreglos altos y mapreduce
R2026bmapreduce en clusters de Spark™ y Hadoop®, y grupos paralelosPuede utilizar Parallel Computing Toolbox™ para evaluar expresiones de arreglos tall en paralelo con un grupo paralelo en el equipo de escritorio. Los arreglos altos permiten ejecutar aplicaciones de Big Data que no caben en la memoria de la máquina. También puede utilizar Parallel Computing Toolbox para escalar el procesamiento de arreglos tall conectándose a un grupo paralelo que se ejecuta en un cluster de MATLAB Parallel Server™. Como alternativa, puede utilizar un cluster de Hadoop habilitado para Spark que ejecute MATLAB Parallel Server. Para obtener más información, consulte Big Data Workflow Using Tall Arrays and Datastores.
Funciones
Clases
Temas
- Big Data Workflow Using Tall Arrays and Datastores
Learn about typical workflows using tall arrays to analyze big data sets.
- Use Tall Arrays on a Parallel Pool
Discover tall arrays in Parallel Computing Toolbox and MATLAB Parallel Server.
- Process Big Data in the Cloud
This example shows how to access a large data set in the cloud and process it in a cloud cluster using MATLAB® capabilities for big data.
- Use Parallel Computing to Optimize Big Data Set for Analysis
This example shows how to optimize data preprocessing for analysis using parallel computing. (Desde R2024a)
- Use Tall Arrays on a Spark Cluster
Create and use tall tables on Spark clusters without changing your MATLAB code.
- Run MapReduce on a Parallel Pool
Try
mapreducefor advanced analysis of big data using Parallel Computing Toolbox. - Run mapreduce on a Hadoop Cluster
Learn about
mapreducefor advanced big data analysis on a Hadoop cluster. - Partition a Datastore in Parallel
Use
partitionto split yourdatastoreinto smaller parts.
Información relacionada
Ejemplos destacados
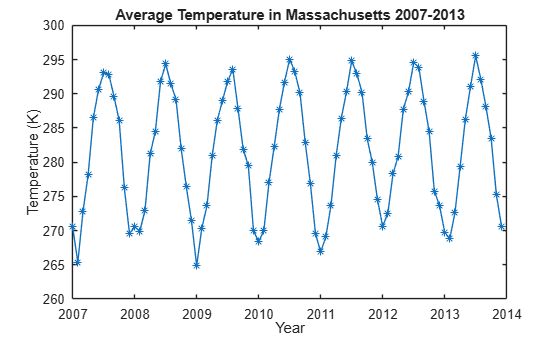
Process Big Data in the Cloud
Access a large data set in the cloud and process it in a cloud cluster using MATLAB® capabilities for big data.
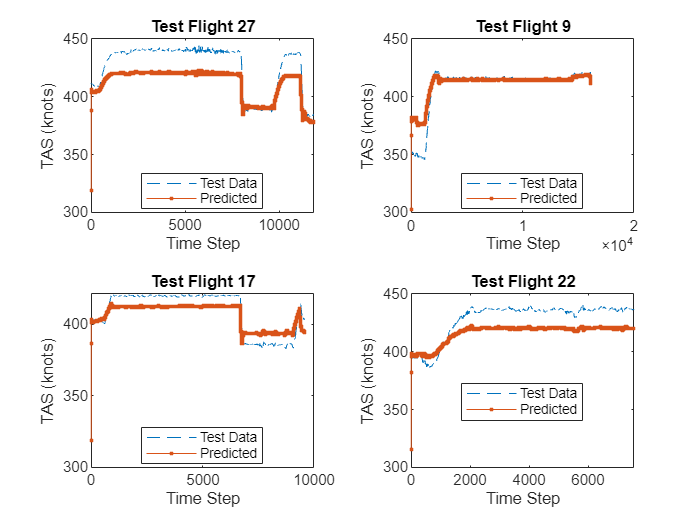
Use Parallel Computing to Optimize Big Data Set for Analysis
Optimize data preprocessing for analysis using parallel computing.

